– 5 of 10
Data Poisoning
By Narasimham Nittala
Artificial Intelligence (AI) is becoming embedded in the way Organizations operate, make decisions and serve customers. The fundamental question today is no longer “Can we use AI?” It is: “Can we use AI responsibly, securely and resiliently at scale?”
As AI becomes more capable and increasingly autonomous, it also becomes a new attack surface. What happens when an AI System / Solution is manipulated, impersonated, poisoned, stolen, compromised or simply goes wrong?
Financial Technology Frontiers (FTF)’s 10–part AI Security Risks Series examines the ten key AI Security Risks highlighted by the Canadian Centre for Cyber Security (CCCS), and goes beyond technology to explore the What, How, Impact and Control of each Risk. This series is designed to give Business Leaders and Technology, Cybersecurity, Risk and Compliance Professionals a practical framework for understanding and managing the manyfaces of AI Risk.
Data Poisoning
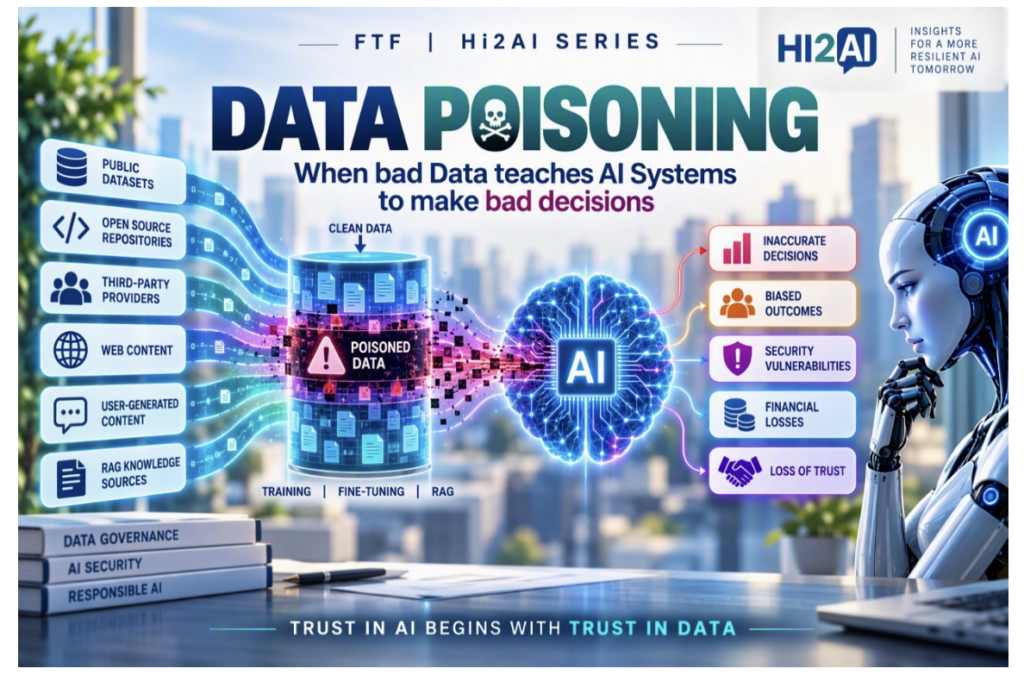
When bad Data teaches AI Systems to make bad decisions
AI Systems are only as trustworthy as the Data that trains, fine–tunes, informs or guides them.
Organizations often focus on protecting AI Models, Applications and Infrastructure. However, if the underlying Data cannot be trusted, the AI System itself may become unreliable regardless of how secure the surrounding technology appears.
Data Poisoning exploits precisely this dependency.
What Is It All About?
Data Poisoning occurs when an attacker deliberately manipulates Data used by an AI System to influence its behaviour, outputs or decisions.
Unlike attacks that target AI Applications directly, Data Poisoning attacks the information that the AI System learns from or relies upon. The objective may be to introduce bias, degrade performance, create vulnerabilities, manipulate outcomes or alter how the AI System responds in specific situations.
According to the National Institute of Standards and Technology (NIST), Data Poisoning is a Cybersecurity Risk in which an adversary compromises Training Data or other Data Sources used by an AI System to influence its operation or outputs. As Organizations increasingly use AI Systems that continuously learn from, retrieve or interact with large amounts of information, protecting the integrity of Data becomes a critical Security and Governance requirement.
How Does This Threat Attack?
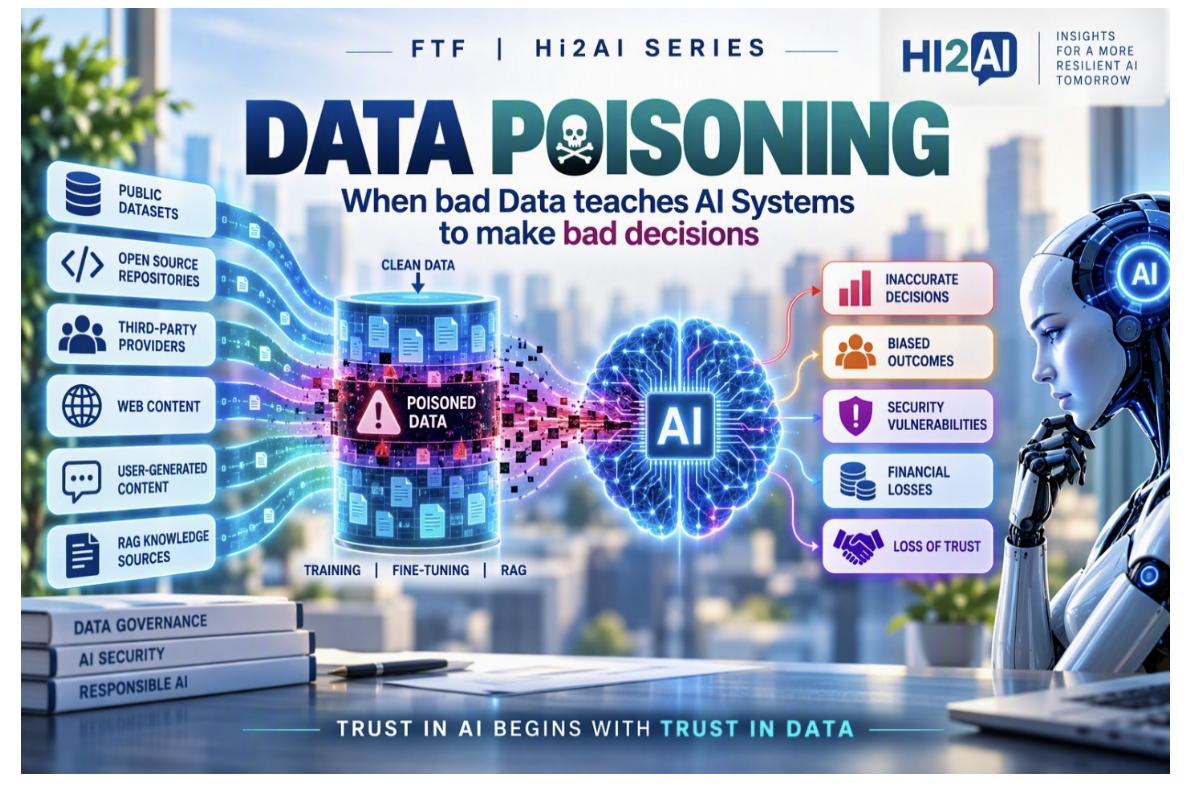
An attacker may attempt to introduce inaccurate, misleading, manipulated or malicious information into Data used by an AI System. The compromised information could enter through one or more of the following routes.
• Public Datasets and Open–Source Repositories. Many AI Systems rely on publicly available Datasets, Open–Source Models and Community–Contributed Resources for Training, Fine–Tuning or Validation. Attackers may deliberately introduce poisoned Data, manipulated Model Components or misleading information into these sources with the expectation that they will be adopted by Organizations. Because these resources are often widely shared and reused, compromised content can spread across multiple AI Systems before being detected.
• Third–Party Data Providers and Supply–Chain Data Feeds. Many Organizations rely on external Data Providers, Partners, Vendors and Service Providers to supply information used by AI Systems. If these sources become compromised, manipulated or insufficiently validated, poisoned information may flow directly into downstream AI Environments. This creates a supply–chain style risk where trust in an external source becomes an avenue for compromise.
• Web–Scraped Content and Internet Sources. AI Systems frequently rely on Data collected from Websites, Social Platforms, Forums and other publicly accessible Internet Sources. Attackers may deliberately publish misleading, inaccurate or malicious content designed to be captured through Data Collection activities. Once ingested into Training Datasets or Knowledge Sources, the poisoned information may influence future AI outputs.
• User–Generated Content. AI Systems that learn from Customer Feedback, User Submissions, Reviews, Ratings or Community Contributions may be vulnerable to manipulation. Attackers may submit large volumes of coordinated misinformation or malicious content designed to influence how the AI System learns, prioritizes information or generates responses. Because the content originates from apparently legitimate users, the manipulation can be difficult to identify.
• Retrieval–Augmented Generation (RAG) Knowledge Sources. AI Systems using Retrieval–Augmented Generation (RAG) rely on external Documents, Knowledge Bases, Databases and Repositories when generating responses. Attackers may compromise these sources or introduce misleading information that appears credible and authoritative. The AI System may then retrieve and use this poisoned information while continuing to generate responses that appear trustworthy and accurate. RAG is an AI approach where an AI System retrieves relevant information from external sources such as documents, databases or knowledge repositories and uses that information to generate its response.
• Compromised Internal Systems, Databases and Data Pipelines. Not all Data Poisoning originates from external actors. Attackers who gain access to Internal Systems, Databases or Data Pipelines may manipulate information before it reaches the AI System. Insider actions, unauthorized changes or accidental Data Corruption can produce similar outcomes, making strong Data Integrity Controls essential throughout the AI Environment.
The objective is not always to cause obvious failure. In many cases, attackers seek to subtly influence AI behaviour while maintaining the appearance of normal operation. A poisoned AI System may continue to generate outputs that appear credible and accurate, making the manipulation difficult to identify until business decisions, operational processes or Security Controls are affected.
What Harm Can This Risk Do?
Compromised Data can have consequences that extend across the entire AI Lifecycle. Potential impacts include, but are not limited to:
• Inaccurate Decisions and Recommendations. An AI System relies on the quality and integrity of the information available to it. When poisoned Data influences the Model, the System may generate recommendations, predictions or decisions that are factually incorrect or operationally inappropriate. Organizations may unknowingly rely on these outputs when making important business, financial or strategic decisions.
• Biased or Discriminatory Outcomes. Manipulated Data may introduce or amplify biases within an AI System. As a result, the AI may produce unfair, inconsistent or discriminatory outcomes across different users, customers or stakeholder groups. Such outcomes can create ethical concerns and expose Organizations to reputational and regulatory scrutiny.
• Reduced AI Performance and Reliability. Data Poisoning can gradually degrade the overall quality and effectiveness of an AI System. Predictions may become less accurate, responses less reliable and decision–making less consistent over time. The Organization may experience declining trust in AI outputs without immediately understanding the underlying cause.
• Compromised Fraud Detection Capabilities. Fraud Detection Systems often rely heavily on historical Data and behavioural patterns. If attackers successfully poison this information, the AI may become less effective at identifying suspicious activity or may incorrectly classify fraudulent transactions as legitimate. This can weaken a critical layer of organizational defence.
• Incorrect Financial, Operational or Business Insights. Many Organizations use AI Systems to generate forecasts, risk assessments, operational insights and strategic recommendations. If poisoned Data influences these outputs, decisionmakers may act on inaccurate information. This can result in poor investments, ineffective resource allocation and flawed business strategies.
• Manipulated AI–Assisted Decision Making. Increasingly, AI Systems influence decisions made by Employees, Managers and Executives. Attackers may exploit Data Poisoning to subtly shape AI–generated recommendations toward specific outcomes. Over time, human decisionmakers may unknowingly be guided by manipulated information that appears legitimate and trustworthy.
• Security Vulnerabilities Embedded Within AI Models. Data Poisoning can be used to deliberately introduce weaknesses into an AI System. Attackers may create hidden behaviours, triggers or patterns that remain dormant until activated under specific conditions. These vulnerabilities may be difficult to identify through conventional Security Testing and could be exploited later to achieve malicious objectives.
• Regulatory and Compliance Exposure. If a poisoned AI System produces inaccurate, biased or harmful outcomes, Organizations may face challenges demonstrating that appropriate Governance, Risk Management and Control processes were in place. Depending on the industry and jurisdiction, this could create Privacy, Consumer Protection, Financial Services or other Regulatory concerns.
• Financial Losses. The financial consequences of Data Poisoning can arise in many forms, including operational errors, fraud, remediation costs, legal expenses, regulatory actions and lost business opportunities. In some cases, Organizations may need to retrain Models, restore datasets and conduct extensive investigations before normal operations can resume.
• Reputational Damage and Loss of Stakeholder Trust. Trust is often one of the most valuable assets an Organization possesses. If an AI System produces inaccurate, biased, unsafe or manipulated outputs, Customers, Employees, Regulators and Business Partners may lose confidence in the Organization’s use of AI. Rebuilding trust can take significantly longer and cost considerably more than preventing the incident in the first place.
The challenge is that Data Poisoning often does not produce immediate or obvious failure. An AI System may continue to function normally while generating outputs that appear credible, consistent and professionally presented. Consequently, Organizations may not discover the manipulation until the resulting decisions, recommendations or actions have already created operational, financial or reputational consequences.
In many cases, the greatest risk is not that the AI System stops working, but that it continues working while quietly making the wrong decisions.
What Can Organizations Do To Control This Risk?
Organizations cannot effectively secure AI Systems without securing the Data that influences them. Unlike conventional Software Systems, AI Systems derive their behaviour, outputs and decisions from the information that trains, finetunes, informs or guides them. As a result, the integrity of the Data itself becomes a critical component of AI Security. Even the most sophisticated AI Model can produce unreliable outcomes if it is influenced by inaccurate, manipulated or untrustworthy Data. Organizations should therefore view Data Protection not simply as a Data Management activity, but as a fundamental AI Governance, Risk Management and Security requirement. Controls should focus on ensuring that Data remains accurate, trustworthy and resilient against manipulation throughout the entire AI Lifecycle, from Data Collection and Training through to Deployment, Operation and Continuous Improvement. Organizations should:
• Establish Strong Data Provenance and Governance. Organizations should maintain clear visibility into where AI Data originates, how it is collected, who has modified it and how it is being used. Data Lineage, Version Control and Auditability help establish trust in the information that trains, fine–tunes or informs AI Systems and support investigations when anomalies occur.
• Validate and Continuously Assess Data Sources. Third–Party Data Providers, Open–Source Datasets, RAG Sources and other external Data Feeds should be continuously evaluated for accuracy, integrity and reliability. Organizations should avoid assuming that trusted sources remain trustworthy indefinitely and should establish processes to identify degraded or compromised Data Sources.
• Protect Critical AI Data Environments. Training, Fine–Tuning, Embedding and RAG Environments should be treated as high–value assets and protected accordingly. Strong Identity Management, Access Controls, Change Management Processes and Segregation of Duties can help prevent unauthorized Data manipulation and reduce the risk of intentional or accidental poisoning.
• Monitor for Data Integrity Issues and Anomalous Behaviour. Organizations should continuously monitor both Data Pipelines and AI Outputs for unexpected changes, unusual patterns or indicators of Data manipulation. Data Anomaly Detection, Integrity Checks and Output Monitoring can help identify poisoning attempts before they result in significant business impact.
• Maintain Recovery and Resilience Capabilities. Organizations should be prepared to respond quickly if Data Poisoning is detected. Maintaining Version–Controlled Datasets, Model Rollback Capabilities and Recovery Procedures enables teams to restore trusted Data and return AI Systems to a known–good state with minimal disruption.
• Regularly Test AI Systems Against Data Poisoning Scenarios. Data Poisoning should be incorporated into AI Security Testing, Red Team Exercises and Risk Assessments. Periodic testing helps Organizations evaluate whether existing controls can detect and withstand attempts to manipulate Data, while also identifying weaknesses before attackers exploit them.
Organizations should recognize that Data Poisoning is not just a Security problem. It is equally a Data Governance, Risk Management and AI Governance challenge.
FTF Analysis
Data Poisoning demonstrates why AI Governance ultimately begins with Data Governance.
Many Organizations focus heavily on securing AI Models, Applications and Infrastructure while treating the Data Pipeline as a secondary concern. In practice, the opposite may be true. An AI System can only be as reliable as the information that shapes its decisions. The critical question is therefore not simply whether an AI Model is performing correctly today. It is whether the Organization can confidently answer:
“Where did this Data come from, who changed it, when was it changed and can it still be trusted?“
If the answer is unclear, then confidence in the AI System itself becomes difficult to justify.
This challenge becomes even more significant as Organizations increasingly adopt RAG Architectures, AI Agents, Continuous Learning Approaches and large interconnected Data Ecosystems. The attack surface is no longer limited to the AI Model. Every Dataset, Knowledge Repository, External Feed, Supplier Integration and Data Pipeline becomes a potential target.
FTF believes that Data Integrity should increasingly be treated as an AI Security Control rather than solely a Data Management concern. Organizations that establish strong controls around Data Provenance, Data Quality, Data Integrity and Data Governance will be better positioned to build AI Systems that remain trustworthy, resilient and defensible even as Data Volumes, AI Capabilities and Threat Techniques continue to evolve.
The question is not whether AI can be trusted. The question is whether the Data shaping that AI can be trusted.
About This Article:
This Article examines one of the most important assumptions underpinning modern AI Systems: that the Data influencing AI decisions can be trusted. It explores how Data Poisoning attacks can compromise that trust, creating risks that may not be immediately visible but can ultimately affect business decisions, Security, compliance and organizational reputation. The Article also considers why Data Governance, Data Integrity and Data Provenance should increasingly be viewed as foundational AI Security controls in an era of connected AI Systems, RAG architectures and autonomous AI Agents.
This Article is authored by Narasimham Nittala who leads the Strategy and Research vertical of Financial Technology Frontiers (FTF). This Article is published as part of FTF’s Hi2AI Series. Like our previously published Articles, this Article is written in an accessible, practitioner–focused format and it aims to raise awareness about responsible AI adoption across various Institutions.
FTF believes that service providers, Fintech entities, consulting firms and technology companies can all benefit from reflecting on the perspectives shared here and consider how their own approaches to AI Risk Management can evolve. Practitioners in various industries are equally encouraged to adapt these insights to their unique contexts.
About Hi2AI
Hi2AI is FTF’s AI ecosystem For Financial Services. Hi2AI is a trusted community shaping the future of Artificial Intelligence in Financial Services by driving responsible innovation, influencing policy with regulators, and crafting future standards that ensure growth, resilience, and trust across the global financial ecosystem. Hi2AI exists to accelerate the responsible adoption of AI across the global financial ecosystem through:
• AI–Driven Industry Collaboration.
• Ecosystem Connection & Innovation.
About Financial Technology Frontiers
Financial Technology Frontiers (FTF) is a global media–led fintech platform dedicated to building and nurturing innovation ecosystems. We bring together thought leaders, financial institutions, fintech disruptors, and technologypioneers to drive meaningful change in the financial services industry.
References